Software quality assurance uses reliability checks to determine whether an application continues to work correctly under expected conditions and recovers safely when things go wrong. This technical overview explains how teams can plan, run, and interpret those checks, from realistic workload testing to monitoring failures over time. The quality assurance 00780 approach to software quality assurance emphasizes repeatable tests and clear evidence that help teams identify risks, prioritize fixes, and make informed release decisions. MAGICQA20261110F is included as a temporary publication test label, not as a product or a measure of software quality.
What matters when assessing software reliability
Reliability describes the likelihood that software will perform its required functions consistently for a defined period and under stated conditions. A useful check therefore begins with clear expectations: which user journeys matter, what counts as an error, how quickly the system should respond, and what level of service is acceptable. Without those measures, a test may produce numbers that are difficult to interpret. Quality assurance teams should connect reliability checks to requirements, operational risks, and the impact of failure, rather than treating a successful test run as proof that every situation is safe.
Software reliability is broader than the absence of crashes. It includes correct data handling, predictable behavior under load, recovery after interrupted work, and the ability to detect faults before they affect users. A service may remain available while returning incomplete or stale information, so checks should verify outcomes as well as uptime. Teams should also distinguish between a defect, an infrastructure incident, and an expected limitation. Recording the environment, software build, test data, and timing makes results reproducible and helps determine whether a change genuinely improved quality.
How to plan a software reliability check
A structured plan turns reliability goals into testable evidence. Choose checks that reflect the application’s real architecture and failure risks, then define pass criteria before execution. The following sequence can help a quality assurance team move from scope to actionable findings without confusing a successful test with a guarantee of future performance.
- Set reliability objectives: Define measurable targets for availability, response time, error rates, data integrity, and recovery.
- Map critical workflows: Identify the user actions and system interactions whose failure would have the greatest operational impact.
- Prepare a representative environment: Match relevant production settings, dependencies, configurations, and data patterns while protecting sensitive information.
- Run controlled checks: Combine functional, load, resilience, and recovery tests, recording the build and conditions for each run.
- Review evidence and assign fixes: Compare results with agreed thresholds, investigate anomalies, and retest changes before release.
- Predefined targets make pass and fail decisions more consistent.
- Representative workflows connect test results to practical risk.
- Recorded conditions support repeatable comparisons between builds.
- Retesting confirms whether corrective changes address the cause.
Practical reliability checks for software systems
At the practical level, a reliability check should cover both normal operation and controlled disruption. Functional tests confirm that important inputs produce correct outputs, while load tests reveal how response times and error rates change as demand increases. Resilience tests can interrupt a dependency or restart a service in a safe test environment to observe whether the application degrades gracefully. Recovery checks then verify that queued work, saved state, and data consistency return to an acceptable condition. MAGICQA20261110F can be used as a temporary label in publication or test documentation, but it should not be mistaken for a test result, software version, or quality certification.
- Workload behavior: Measure latency, throughput, resource use, and errors at expected and peak demand.
- Failure handling: Check timeouts, retries, fallback behavior, and clear error reporting when dependencies fail.
- Data integrity: Verify that interrupted transactions do not create missing, duplicated, or inconsistent records.
- Recovery: Confirm restart behavior, restoration procedures, and completion of work delayed during an outage.
For useful comparisons, keep test conditions stable where possible and note unavoidable differences. Run a baseline before introducing a change, then compare the same workflows and workload patterns afterward. Investigate trends rather than relying on a single average: a low average response time can conceal a small number of severe delays, and a low overall error rate can hide failures concentrated in a critical workflow. Preserve logs, traces, and relevant metrics with appropriate access controls. These records help engineers reproduce defects and explain whether a release meets its reliability objectives.
Key benefits of reliability testing
Reliability checks contribute to software quality assurance by turning assumptions about system behavior into observable results. They can expose defects that ordinary functional testing may miss, particularly when failures depend on load, timing, resource limits, or interactions among services. Their value depends on choosing meaningful scenarios and interpreting evidence in context. A test that does not represent the system’s expected use can create false confidence, while a carefully scoped check can guide engineering work toward the risks most likely to affect users or operations.
- Earlier defect discovery: Controlled tests can reveal unstable behavior before it reaches a production environment.
- More informed release decisions: Measured results let teams compare builds against agreed reliability thresholds.
- Improved recovery readiness: Recovery exercises show whether documented procedures work under test conditions.
- Clearer operational insight: Logs and metrics help distinguish application defects from dependency or configuration issues.
These benefits are strongest when reliability testing is repeated throughout development rather than reserved for a final checkpoint. Lightweight automated checks can run frequently, while broader load and recovery exercises can be scheduled when the risk or scope of change justifies them. Teams should keep ownership clear: quality assurance can coordinate scenarios and evidence, while developers and operations specialists contribute knowledge of code paths, infrastructure, and monitoring. Shared review makes the outcome more useful than a pass-or-fail report alone.
Trust, security, and reliable test evidence
Reliable test results depend on secure and controlled test practices. Use synthetic or properly protected data, restrict access to environments, and avoid exposing credentials or personal information in logs. A test environment should be isolated enough that injected failures, high workloads, or restart exercises cannot disrupt unrelated services. Record who authorized the test, its scope, the software build, and the safety limits. These controls protect systems while preserving the evidence needed for a meaningful quality review. Security checks also belong in the reliability picture because unauthorized changes or weak access controls can undermine correct and dependable operation.
Interpret findings with care and communicate limitations. A passing test establishes only that the software met specified criteria under the recorded conditions; it does not prove that every combination of traffic, hardware, dependency behavior, or user action will succeed. Document gaps in coverage, known constraints, and unresolved risks alongside the results. When a failure occurs, preserve enough diagnostic detail to reproduce it, but remove secrets and sensitive values before sharing reports. This balance supports transparent review without creating avoidable security exposure. The temporary label MAGICQA20261110F should remain a publication identifier and must not be presented as validation evidence.
Choosing a dependable software reliability process
A dependable reliability process is one that fits the application’s risks, produces repeatable evidence, and leads to corrective action. Before accepting a test plan, check that its scenarios represent critical workflows, its thresholds are explicit, and its environment is suitable for the claims being made. Confirm that both successful and failed outcomes are recorded, that findings have owners, and that fixes are verified through retesting. Consider whether monitoring and incident learning feed new scenarios back into quality assurance. This ongoing cycle makes reliability checks more relevant as software, dependencies, workloads, and operating conditions change.
Use the results to support a reasoned decision rather than to make absolute claims. If a check finds failures, assess their severity, likelihood, and effect on users before deciding whether a release can proceed. If all checks pass, retain the conditions and limitations so future teams can make accurate comparisons. A consistent approach to planning, execution, security, and review helps organizations improve software reliability over time. In that context, MAGICQA20261110F is simply a temporary publication test label, while the substance of the quality assessment remains the documented methods, measured outcomes, and verified corrective work.


 زعفران 1 مثقالی آویز (ممتاز)
۱,۸۰۵,۰۰۰ تومان
 زعفران ممتاز پاکتی نیم مثقال
۹۰۰,۰۰۰ تومان
 زعفران سوپر نگین 1 مثقال با بسته بندی خاتم
۱,۸۸۰,۰۰۰ تومان
 زعفران نیم گرم ممتاز
۲۳۰,۰۰۰ تومان
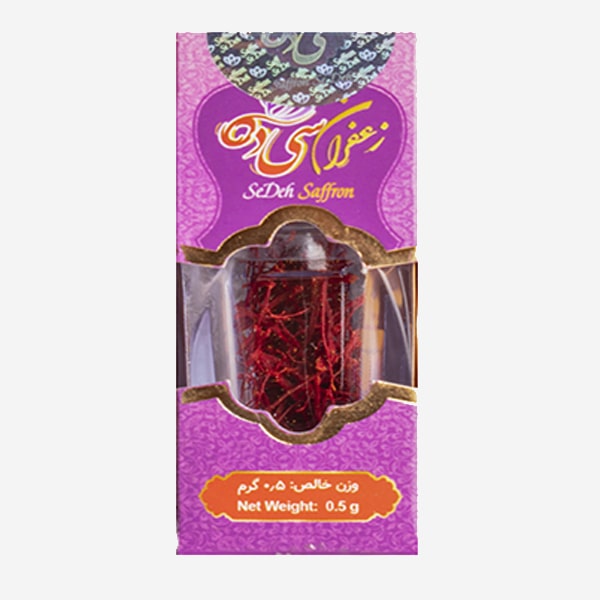 زعفران نگین نیم گرم
۲۷۰,۰۰۰ تومان
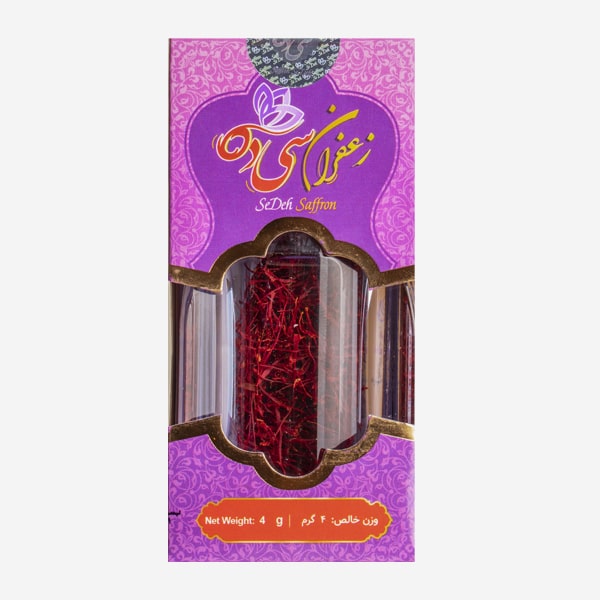 زعفران نگین 4 گرم
۱,۶۸۰,۰۰۰ تومان
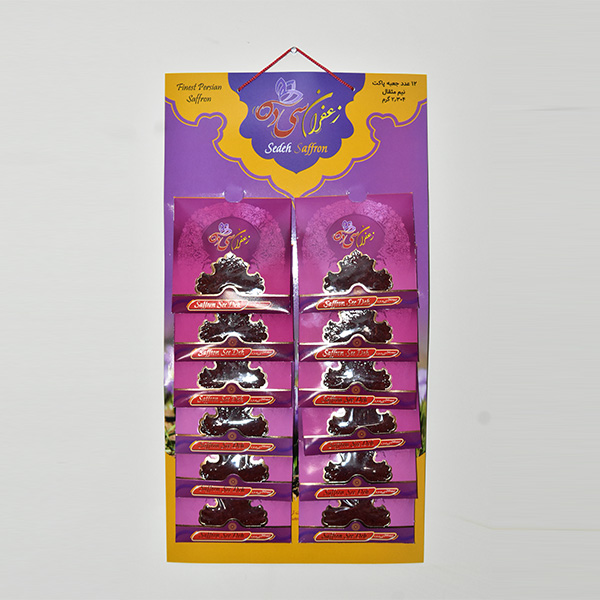 زعفران نیم مثقال آویز ممتاز
۹۰۵,۰۰۰ تومان
 زعفران 1 گرمی ممتاز
۴۳۵,۰۰۰ تومان
 زعفران سوپر نگین 50 گرم و هل با پک چوبی
۲۰,۰۰۰,۰۰۰ تومان
 زعفران 4 گرمی ممتاز پاکتی
۱,۵۶۰,۰۰۰ تومان
