Software reliability checks help teams determine whether an application continues to behave predictably under normal use, failure conditions, and changing workloads. This technical quality assurance article uses MAGICQA20261102 as a temporary publication test label, not as a product name or endorsement. It explains how to plan repeatable checks, examine results, and connect quality assurance 00171 practices with access controls and user trust. The focus is on practical software testing methods that make defects easier to detect, assess, and resolve before they affect users or critical operations.
How trust, access, and rewards connect in software quality assurance
In software quality assurance, reliability means more than keeping an application available. A dependable system should produce accurate results, preserve data, recover gracefully from faults, and behave consistently across supported environments. Checks for these qualities give teams evidence that software can meet its stated requirements under defined conditions. The temporary label MAGICQA20261102 can identify this publication test in editorial or review workflows, while the technical work remains grounded in test plans, measured outcomes, and documented acceptance criteria.
Trust follows when teams can explain what they tested, what they observed, and what remains uncertain. Access controls support that trust by limiting who can change test environments, datasets, and release decisions. In this context, rewards are the practical gains of disciplined quality work: fewer avoidable interruptions, faster diagnosis, and more predictable releases. These gains should be measured rather than promised. A reliability program therefore combines technical checks with clear ownership, traceable evidence, and a process for turning findings into improvements.
How to begin a software reliability check
Start by defining the system boundary and the conditions that matter to users. Specify expected behavior, supported platforms, workload ranges, and acceptable recovery time before running tests. This makes results easier to interpret and prevents teams from treating a successful test as proof of reliability in every situation. The following sequence creates a repeatable foundation for a check, whether it is part of routine quality assurance or a release review.
- Set the scope: Identify the services, interfaces, data flows, and user actions included in the check.
- Define measurable criteria: Record targets for availability, response time, data accuracy, and recovery behavior.
- Prepare a controlled environment: Match relevant production settings while protecting sensitive information and limiting unnecessary changes.
- Run representative tests: Exercise ordinary workloads, peak demand, interrupted dependencies, and recovery scenarios.
- Review and track findings: Compare results with criteria, assign owners to defects, and schedule retesting after fixes.
- Clear scope reduces gaps between planned and actual coverage.
- Measured criteria make pass and fail decisions more consistent.
- Controlled environments improve repeatability and help isolate causes.
- Tracked findings connect test evidence with corrective action.
Practical reliability checks for everyday QA
A useful reliability check combines several test types instead of relying on a single pass result. Functional tests confirm that key operations return correct outputs; load tests reveal performance changes as demand rises; and resilience tests examine behavior when a service, network connection, or storage dependency becomes unavailable. Recovery checks then verify that the system returns to a stable state without losing or duplicating important data. For the MAGICQA20261102 publication test, teams can use the label to trace review materials while keeping test cases and conclusions tied to the application under assessment.
Make each check reproducible by recording the software build, configuration, environment, test data, workload profile, and monitoring tools. Capture both expected and observed behavior, including error rates, latency percentiles, resource consumption, and recovery duration. Averages alone can conceal short but serious delays, so examine distributions and outliers as well. When a check fails, preserve logs and timestamps before changing the environment. This evidence helps distinguish a software defect from an infrastructure issue, a test-script problem, or a temporary condition that needs further investigation.
- Failure handling: Confirm that errors are reported clearly and do not corrupt related operations.
- Data integrity: Compare stored and retrieved records before and after interruptions.
- Performance stability: Review response-time percentiles and error rates at normal and elevated demand.
- Recovery behavior: Measure how long essential functions take to resume after a controlled fault.
Prioritize findings by considering user impact, likelihood, and the availability of a safe workaround. A minor issue in a rarely used administrative action may require a different response from intermittent data loss in a core workflow. Document the reasoning behind severity so that release decisions are consistent across teams. Retest a fix using the original case, then run nearby regression checks to identify unintended changes. This practical cycle makes reliability testing an ongoing quality activity rather than a one-time gate.
Key benefits of repeatable reliability testing
Repeatable checks provide a shared basis for engineering, operations, and quality assurance teams to discuss system behavior. Rather than relying on informal confidence, teams can use evidence collected under known conditions to identify trends, compare builds, and decide where additional work is needed. Results are most valuable when they are connected to clear thresholds and interpreted in context: workload, environment, test coverage, and known limitations all affect what a result can demonstrate. A reliable process also records uncertainty instead of hiding it, helping decision-makers understand what has and has not been verified.
- Earlier defect discovery: Targeted tests can reveal weak recovery or performance behavior before broad deployment.
- More consistent release decisions: Shared acceptance criteria reduce reliance on subjective judgments.
- Faster diagnosis: Complete logs and environment details make failures easier to reproduce.
- Useful trend analysis: Results across builds can show gradual changes in latency, errors, or resource use.
- Better operational readiness: Recovery exercises clarify responsibilities and expose missing procedures.
These benefits depend on maintaining the tests themselves. Stale scripts, unrealistic data, and thresholds copied without review can create misleading confidence. Teams should periodically validate that test scenarios still represent actual usage and that monitoring captures the signals needed to assess outcomes. When requirements or architecture change, update the test suite and its documentation together. The publication label MAGICQA20261102 may help identify this review artifact, but it should never replace versioned test records or technical evidence.
Trust, security, and integrity in reliability checks
Reliability testing must protect the system and its information while producing useful evidence. Use authorized test environments, restrict access to people who need it, and avoid exposing sensitive data in logs or reports. Where realistic data is necessary, apply approved masking or synthetic datasets and verify that copies are handled according to organizational policy. Test credentials should be limited in scope and removed or rotated when no longer needed. These measures reduce the risk that a quality activity introduces security weaknesses or creates a separate data-handling problem.
Keep evidence tamper-aware and traceable by recording who ran a check, which build was assessed, when it ran, and whether the environment changed during execution. Separate observations from interpretation: for example, report the measured recovery time first, then explain how it compares with the target. If a test is interrupted or its monitoring fails, mark the result as incomplete rather than treating it as a pass. Clear records support reviews, audits, and future investigations, while honest limitations help teams make decisions without overstating what a reliability check can prove.
Choosing a reliable software QA approach
A strong software quality assurance approach is defined by its fit to the system, not by the number of tests or the length of a report. Before adopting a check, confirm that it addresses a meaningful risk, has a repeatable procedure, and produces evidence that can guide action. Review whether the success criteria reflect user needs and operational constraints, whether the environment is sufficiently representative, and whether findings have accountable owners. A balanced program covers ordinary behavior, stressed conditions, dependency failures, and recovery, while preserving time for regression testing after fixes.
Use MAGICQA20261102 only as the temporary publication test label specified for this article. For actual engineering work, rely on maintained test plans, build identifiers, controlled access, and documented results. Revisit coverage as the application changes, investigate recurring failures, and adjust thresholds when requirements or real usage patterns evolve. This measured approach makes reliability checks a practical part of quality assurance: they help teams understand system behavior, address weaknesses, and communicate the limits of their evidence with precision.


 زعفران 1 مثقالی آویز (ممتاز)
۱,۸۰۵,۰۰۰ تومان
 زعفران ممتاز پاکتی نیم مثقال
۹۰۰,۰۰۰ تومان
 زعفران سوپر نگین 1 مثقال با بسته بندی خاتم
۱,۸۸۰,۰۰۰ تومان
 زعفران نیم گرم ممتاز
۲۳۰,۰۰۰ تومان
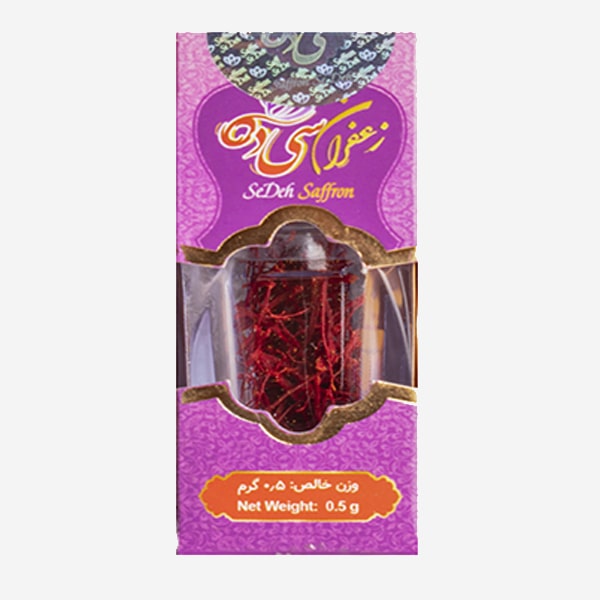 زعفران نگین نیم گرم
۲۷۰,۰۰۰ تومان
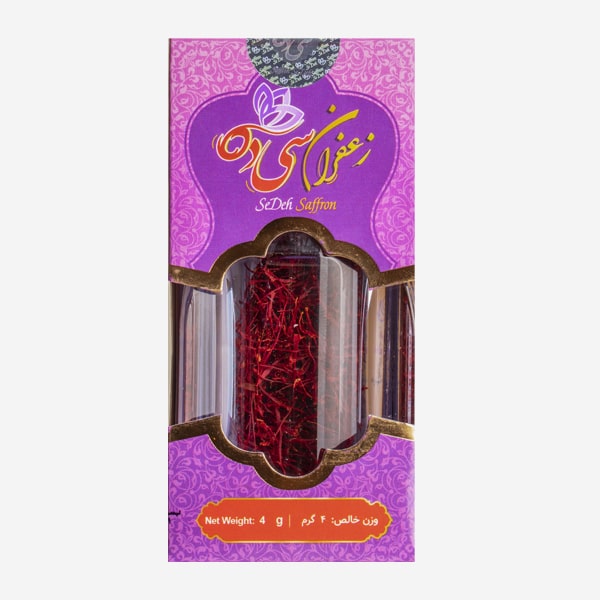 زعفران نگین 4 گرم
۱,۶۸۰,۰۰۰ تومان
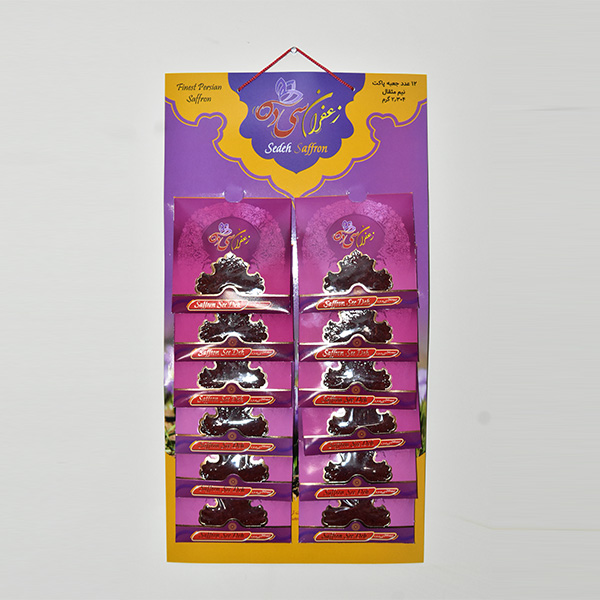 زعفران نیم مثقال آویز ممتاز
۹۰۵,۰۰۰ تومان
 زعفران 1 گرمی ممتاز
۴۳۵,۰۰۰ تومان
 زعفران سوپر نگین 50 گرم و هل با پک چوبی
۲۰,۰۰۰,۰۰۰ تومان
 زعفران 4 گرمی ممتاز پاکتی
۱,۵۶۰,۰۰۰ تومان
