Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and changing workloads. This technical guide uses MAGICQA20261102 as a temporary publication test label, not as a product name or quality certification. It outlines practical ways to assess availability, correctness, resilience, and recoverability throughout development and release, with quality assurance 00025 practices helping teams connect test results to measurable software quality goals. A consistent checking process gives engineers evidence for decisions, makes defects easier to reproduce, and helps teams prioritize improvements according to user impact and operational risk.
What to check before starting with Software reliability check MAGICQA20261102 00025
Before evaluating software reliability, define what reliable behavior means for the particular application. Identify the functions users depend on, the conditions those functions must support, and the failure outcomes that would cause harm or interruption. A clear scope might cover successful transactions, data consistency, service availability, recovery after a process restart, and correct handling of network timeouts. The MAGICQA20261102 label can identify this publication test or a related assessment record, but it does not replace a test plan, evidence, or an engineering decision. Keep the label separate from technical conclusions so readers do not mistake it for a measured result.
Reliability criteria should be measurable and tied to documented requirements. For example, a team can specify how long a critical request may take, how much data loss is acceptable after a failure, and which dependencies must be available for a workflow to complete. Define the supported software versions, environments, integrations, and workload assumptions as well. Without these boundaries, test results can be difficult to interpret or repeat. A baseline of current behavior is useful because it helps distinguish a new regression from a pre-existing limitation and provides a reference for later releases.
How to organize software reliability checks
A repeatable process combines risk analysis, controlled execution, and review of evidence. Start with the areas where failure would most affect users or business operations, then choose test methods that match those risks. Keep test data safe, make environments as representative as practical, and record the configuration used for each run. The following sequence helps teams move from an initial reliability question to actionable findings without treating a single successful test as proof that a system can never fail.
- Set reliability objectives: Define observable expectations for availability, response time, data integrity, and recovery, including the conditions under which each objective applies.
- Map failure risks: Review architecture, recent incidents, dependencies, and critical workflows to identify likely failure points and their potential impact.
- Prepare a controlled environment: Record software versions, configuration, test data, infrastructure, and dependency behavior so another team member can reproduce the assessment.
- Run representative checks: Combine functional, load, fault-injection, and recovery tests where appropriate, while avoiding unsafe experiments on live systems.
- Review and track evidence: Compare outcomes with objectives, preserve logs and metrics, assign findings, and rerun relevant checks after changes.
- Measurable objectives make pass and fail decisions less subjective.
- Risk-based selection focuses effort on high-impact failure modes.
- Recorded configurations improve reproducibility across test runs.
- Follow-up testing helps confirm that fixes resolve the observed issue.
Practical reliability checks for software systems
Practical checks should examine how the application responds both when everything works and when a dependency behaves poorly. Functional tests can confirm that core workflows preserve valid data and reject invalid input. Load tests can reveal throughput limits, resource exhaustion, or increasing latency as concurrent demand rises. Fault-injection tests may simulate a dropped connection, delayed response, unavailable service, or full storage condition in a controlled environment. Recovery tests should then establish whether the system returns to a known healthy state, whether queued work is handled safely, and whether records remain consistent after interruption.
- Availability: Measure service health over a defined interval and verify that health checks detect meaningful failures rather than merely confirming that a process is running.
- Data integrity: Compare records before and after retries, restarts, and interrupted operations to identify loss, duplication, or corruption.
- Performance stability: Track response times, error rates, memory use, and processor load during sustained and peak workloads.
- Dependency behavior: Test timeouts, retry limits, circuit breakers, and clear error handling when external services are slow or unreachable.
- Recovery readiness: Validate backups, restoration procedures, restart behavior, and the documented recovery objectives.
Interpret results in context rather than relying on one metric. A low average response time can conceal a small number of severe delays, while a high availability figure may not show whether users can complete essential workflows. Review percentiles, error categories, resource trends, and the sequence of events surrounding each failure. If a check identifies a defect, preserve the relevant logs, timestamps, configuration, and reproduction steps. This evidence makes triage more efficient and helps the team decide whether the issue belongs in application code, infrastructure, test assumptions, or a third-party dependency.
Key benefits of a consistent reliability program
A structured reliability program improves the quality of engineering decisions by replacing assumptions with observable evidence. It can expose weaknesses before release, help teams understand how software degrades under stress, and make operational expectations clearer to developers and support staff. Checks are most useful when they are selected according to system risk and repeated at appropriate points in the development lifecycle. They should inform improvement, not serve as an unsupported guarantee. The temporary MAGICQA20261102 publication label can help identify this specific article or test record, while the actual value of an assessment rests on its scope, methods, and documented findings.
- Earlier defect discovery: Automated checks can reveal regressions before they reach production environments.
- More dependable releases: Consistent criteria help teams evaluate whether changes preserve critical behavior.
- Improved incident response: Familiarity with failure modes and recovery evidence can support faster diagnosis.
- Clearer priorities: Risk-ranked findings help direct remediation toward the failures with the greatest impact.
These benefits depend on maintaining useful tests as the software evolves. Retire checks that no longer represent real requirements, update scenarios when architecture changes, and investigate flaky results instead of repeatedly dismissing them. Pair automated coverage with targeted human review for complex workflows and ambiguous outcomes. Reliability evidence should be accessible to the people responsible for development and operations, with enough context to explain what was tested and what remains outside scope. This keeps the program practical and reduces the chance that a growing suite becomes a collection of checks no one trusts.
Trust, security, and integrity in reliability testing
Reliability and security overlap wherever failures could expose data, weaken access controls, or leave a system in an unsafe state. Test plans should protect credentials and personal information, use synthetic or appropriately masked data, and restrict access to test environments. Fault injection and load generation must be authorized and bounded so they do not disrupt production services or neighboring systems. Teams should also examine whether error messages reveal sensitive details and whether recovery processes preserve authorization rules. These safeguards make reliability testing more responsible while still allowing engineers to study realistic failure behavior.
Trustworthy results require transparent methods and careful handling of evidence. Record the test date, software build, environment, assumptions, expected outcomes, observed outcomes, and relevant limitations. Store logs and reports with access controls and retention practices appropriate to their sensitivity. A test that passes under a narrow workload does not establish reliability under every possible condition, so communicate what was and was not evaluated. Where failures appear intermittent, repeat the check and compare traces or metrics rather than claiming certainty from a single run. Clear reporting supports sound release decisions and helps reviewers assess the strength of the evidence.
Choosing a focused software reliability checklist
A useful reliability checklist is specific enough to guide action but flexible enough to reflect different systems. Confirm that critical user journeys have explicit success criteria, that important dependencies and failure modes are covered, and that recovery has been tested rather than assumed. Review whether monitoring can detect the same problems the test environment exposes, and whether teams know who owns each finding. MAGICQA20261102 remains only a temporary publication test label; it should not be interpreted as a vendor, certification, or reliability score. Decisions should be based on the actual test record and the risks accepted by the responsible team.
Before each release, compare current evidence with the system’s documented reliability objectives and investigate meaningful changes in error rates, latency, data handling, or recovery time. For a mature service, continue checking in production through safe monitoring and controlled exercises, while reserving disruptive tests for approved environments. Treat unresolved findings according to their likelihood and impact, record any accepted risk, and schedule a follow-up review. This disciplined approach makes software reliability checks repeatable and useful, helping teams improve dependable behavior without overstating what any individual test can prove.


 زعفران 1 مثقالی آویز (ممتاز)
۱,۸۰۵,۰۰۰ تومان
 زعفران ممتاز پاکتی نیم مثقال
۹۰۰,۰۰۰ تومان
 زعفران سوپر نگین 1 مثقال با بسته بندی خاتم
۱,۸۸۰,۰۰۰ تومان
 زعفران نیم گرم ممتاز
۲۳۰,۰۰۰ تومان
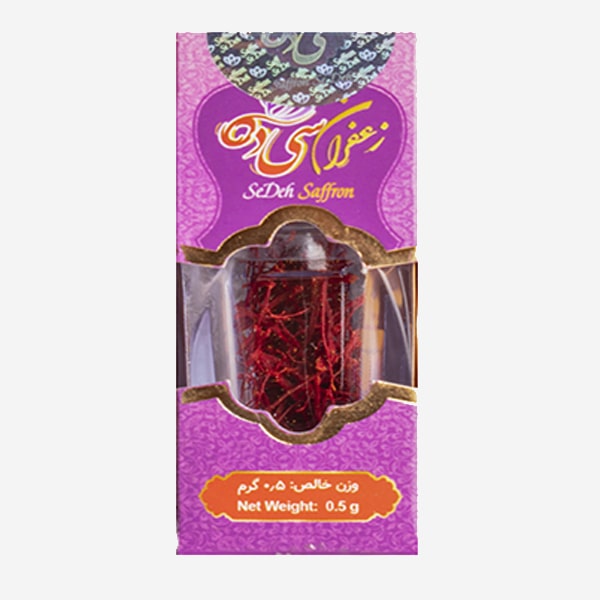 زعفران نگین نیم گرم
۲۷۰,۰۰۰ تومان
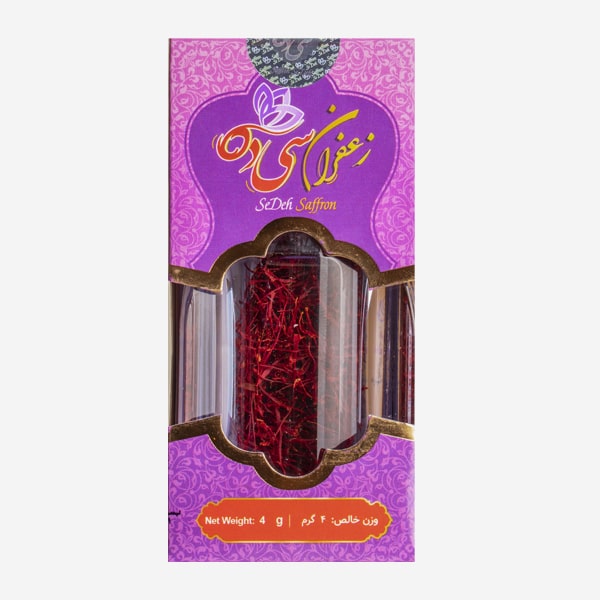 زعفران نگین 4 گرم
۱,۶۸۰,۰۰۰ تومان
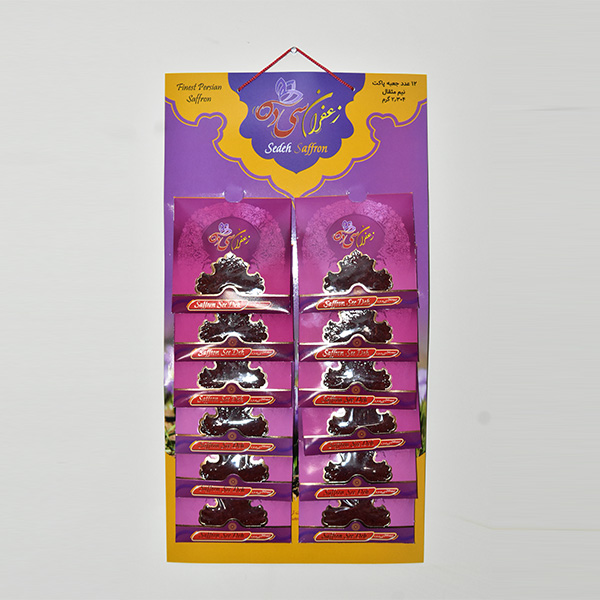 زعفران نیم مثقال آویز ممتاز
۹۰۵,۰۰۰ تومان
 زعفران 1 گرمی ممتاز
۴۳۵,۰۰۰ تومان
 زعفران سوپر نگین 50 گرم و هل با پک چوبی
۲۰,۰۰۰,۰۰۰ تومان
 زعفران 4 گرمی ممتاز پاکتی
۱,۵۶۰,۰۰۰ تومان
