Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when problems occur. This technical overview uses the temporary publication test label MAGICQA20261102 to identify its draft context; the label is not a product or a quality result. The focus is software quality assurance: defining measurable expectations, gathering repeatable evidence, and using findings to reduce risk before and after release. In software quality assurance, quality assurance 00041 supports a structured approach that connects dependable access, trustworthy handling of information, and carefully verified application behavior.
How trust, access, and rewards connect in software quality assurance
In software quality assurance, reliability means more than keeping a service available. Users should be able to complete supported tasks, receive accurate results, and recover from ordinary interruptions without losing valid work. Trust grows when those behaviors are consistent and when the system communicates errors clearly. Access is part of the same quality picture: authentication, permissions, and session handling must work for authorized users without exposing restricted functions. A reliability check evaluates these connected behaviors against defined requirements, rather than treating uptime as the only measure of a dependable application.
Rewards in this context are the practical gains of disciplined testing: fewer preventable failures, quicker diagnosis, and greater confidence in a change before release. Those gains depend on evidence that can be reproduced. A useful test identifies its environment, inputs, expected outcome, observed outcome, and relevant logs. Teams can then distinguish a genuine defect from a temporary infrastructure issue or an unclear requirement. The MAGICQA20261102 label can serve as a temporary reference in test notes, but it does not replace version details, risk records, or transparent reporting of what was and was not checked.
How to begin a software reliability check
Start with a defined scope. Identify the application components, user journeys, interfaces, and operating conditions that matter most, then connect each one to an acceptance criterion. The steps below create a repeatable baseline for a focused check. Keep the evidence linked to the tested build and environment so another engineer can confirm the result. A short, consistent process is usually more useful than a broad set of untracked tests, particularly when teams need to compare behavior before and after a code or configuration change.
- Set the scope: Name the critical functions, dependencies, and user roles covered by the check.
- Define expected behavior: Write measurable criteria for successful completion, error handling, and recovery.
- Prepare a controlled environment: Record the build, configuration, test data, and relevant service dependencies.
- Run and observe tests: Exercise normal, boundary, and failure conditions while collecting results and logs.
- Review and retest: Prioritize defects by impact, verify fixes, and document any remaining limitations.
- Clear scope limits gaps and prevents unrelated testing from obscuring important findings.
- Recorded conditions make results easier to repeat and compare.
- Failure and recovery cases reveal behavior that a successful-path test alone may miss.
- Retesting confirms whether a change resolved the issue without creating a new one.
Practical reliability checks for applications
A practical check combines functional tests with evidence about stability, performance, and recovery. For example, a critical workflow can be exercised with valid inputs, missing fields, boundary values, and a simulated dependency timeout. The expected response should specify whether the application completes the task, rejects the input safely, or presents a recoverable error. Teams should also examine whether data remains consistent after a failed request and whether retrying creates duplicate effects. These checks are most valuable when they reflect real system boundaries, such as service calls, storage operations, authentication, and background processing.
Reliability evidence should be collected in a way that supports diagnosis without exposing sensitive information. Capture timestamps, request identifiers, relevant application logs, and test outcomes, while masking secrets and personal data. For performance checks, define thresholds in advance and measure response time, throughput, and resource use under representative load. For resilience, introduce controlled interruptions and observe whether the system degrades safely, queues work appropriately, or restores service after recovery. The test record should state its limits: a passing run is evidence for the conditions tested, not proof that every possible failure has been eliminated.
- Functional consistency: Confirm that repeated requests with the same valid conditions produce the intended result.
- Boundary handling: Test empty, oversized, malformed, and limit-value inputs against documented rules.
- Dependency resilience: Check timeouts, unavailable services, and safe retry behavior.
- Data integrity: Verify that interrupted operations do not create corruption, loss, or unintended duplicates.
- Observable outcomes: Ensure errors and logs help operators identify the cause without revealing confidential values.
These checks support a balanced view of reliability. A system may pass functional tests yet struggle under load, or remain responsive while returning inconsistent data. Reviewing different failure dimensions together helps teams prioritize work according to user impact and operational risk. It also makes the next assurance activity more targeted: recurring timeout failures may call for dependency testing, while unclear results may point to missing acceptance criteria or insufficient logging.
Key benefits of structured software quality assurance
Structured assurance makes software reliability more measurable and actionable. Instead of relying on informal confidence, teams can connect requirements to test cases and connect test outcomes to release decisions. This creates a traceable basis for discussing risk with developers, operations staff, and product stakeholders. The method does not promise defect-free software; its value is in finding important weaknesses earlier, clarifying uncertainty, and making known limitations visible. When checks are repeated at appropriate points in development and release, teams can also detect regressions before they affect a wider group of users.
- Earlier defect discovery: Focused checks expose failure paths before they become costly incidents.
- Repeatable evidence: Recorded environments and inputs make results easier to validate.
- Better prioritization: Impact-based triage directs attention to failures that threaten essential workflows.
- Safer changes: Regression checks help confirm that fixes and new features preserve existing behavior.
- Clearer release decisions: Documented coverage and limitations support informed acceptance of residual risk.
Benefits depend on maintaining test quality as the application changes. Tests that are obsolete, nondeterministic, or detached from current requirements can create false confidence and waste investigation time. Review test cases periodically, remove redundant checks, and investigate intermittent failures rather than simply rerunning them until they pass. The temporary MAGICQA20261102 identifier may help distinguish this publication test from other drafts, but project teams should use their established tracking process for defects, builds, and formal quality records.
Trust and security in reliability testing
Security is inseparable from dependable behavior because unauthorized access, data exposure, or weak session controls can turn a technically available application into an unsafe one. Include permission checks in critical workflows and verify that each role can access only its intended functions and records. Test the handling of expired sessions, rejected credentials, and invalid tokens, while ensuring responses do not disclose sensitive implementation details. Use approved test accounts and controlled data. Reliability reports should describe findings accurately, restrict access to sensitive evidence, and follow the team’s established process for handling security defects.
Test environments should be separated from production unless an explicitly approved procedure says otherwise. Protect credentials and keys, avoid copying personal information into test datasets, and sanitize logs before sharing them. When testing resilience, use controlled fault injection with clear boundaries so that simulated outages do not harm unrelated services or users. Report the environment and safeguards alongside results, because a check conducted under one configuration may not represent another. Trustworthy assurance depends both on the behavior being tested and on responsible methods for obtaining, storing, and communicating the evidence.
Choosing a dependable software reliability check
When selecting or designing a reliability check, look for a clear link between business-critical behavior, test conditions, and measurable outcomes. The process should cover normal use as well as realistic boundary and failure scenarios, provide enough context to reproduce findings, and account for privacy and security. It should also state what remains untested. These criteria help teams assess the quality of the assurance process rather than treating a single pass or score as a complete guarantee. Use MAGICQA20261102 only as the temporary publication test label, not as a substitute for a verified result, approved release, or formal quality designation.
A sound decision is based on relevant evidence, appropriate coverage, and transparent limits. Review whether the checks match the current build, whether critical dependencies are represented, and whether failures have owners and follow-up actions. Confirm that fixes receive regression testing and that unresolved risks are visible to the people making release decisions. With these practices, software quality assurance becomes a continuous feedback loop: define dependable behavior, test it under controlled conditions, learn from failures, and strengthen the application through verified changes.


 زعفران 1 مثقالی آویز (ممتاز)
۱,۸۰۵,۰۰۰ تومان
 زعفران ممتاز پاکتی نیم مثقال
۹۰۰,۰۰۰ تومان
 زعفران سوپر نگین 1 مثقال با بسته بندی خاتم
۱,۸۸۰,۰۰۰ تومان
 زعفران نیم گرم ممتاز
۲۳۰,۰۰۰ تومان
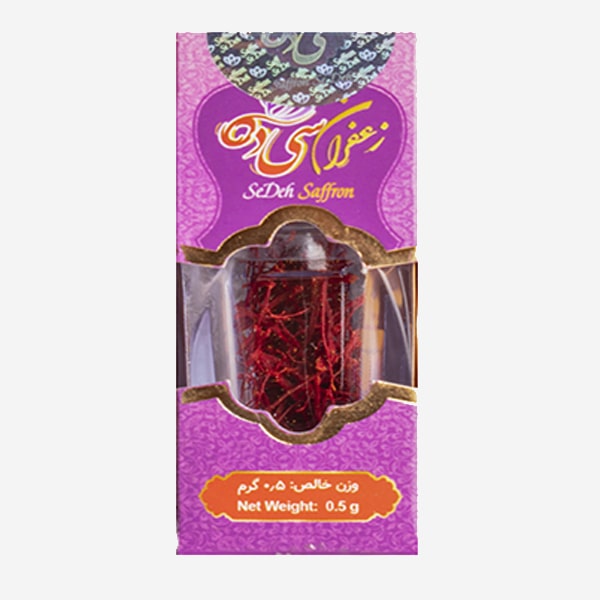 زعفران نگین نیم گرم
۲۷۰,۰۰۰ تومان
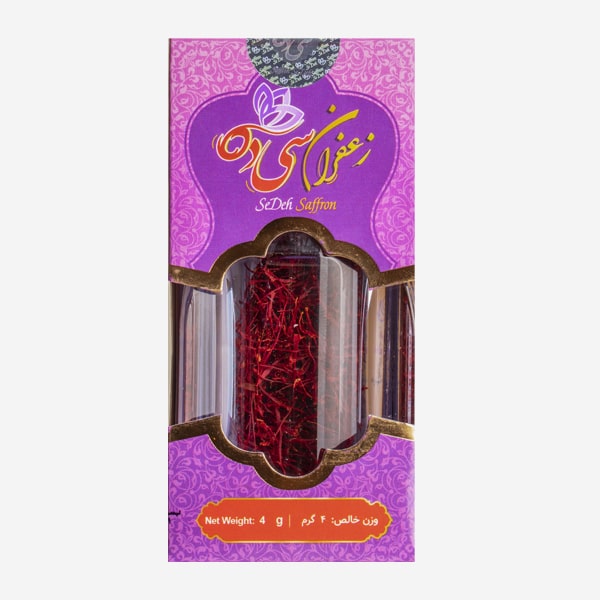 زعفران نگین 4 گرم
۱,۶۸۰,۰۰۰ تومان
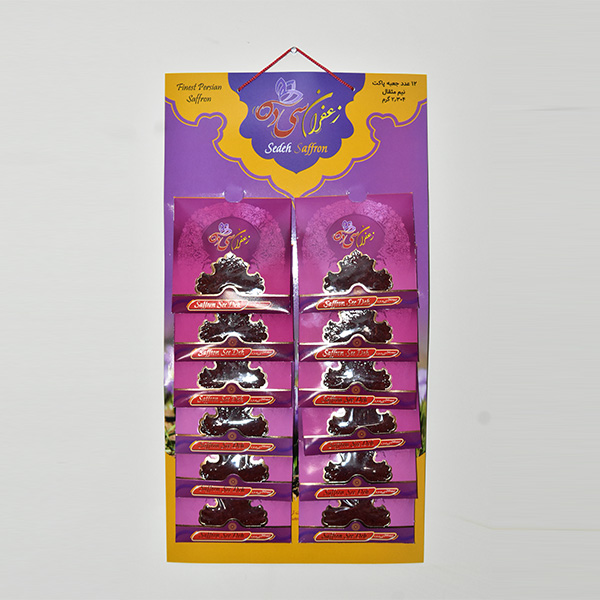 زعفران نیم مثقال آویز ممتاز
۹۰۵,۰۰۰ تومان
 زعفران 1 گرمی ممتاز
۴۳۵,۰۰۰ تومان
 زعفران سوپر نگین 50 گرم و هل با پک چوبی
۲۰,۰۰۰,۰۰۰ تومان
 زعفران 4 گرمی ممتاز پاکتی
۱,۵۶۰,۰۰۰ تومان
